codearia-sieve
Open on GitHubAn open-source parser that prepares a page for a judge rather than a reader: dates as dates, numbers with units, chunks sized to a decision model's window, and the token bill before and after. MCP server and library, MIT, no model and no key.
npx -y codearia-sieveWhat it does
An agent that needs a web page fetches the whole thing: navigation, cookie banner, footer, ad slots and a megabyte of framework markup. Then a model paid per token digs through the pile for one paragraph. codearia-sieve does the digging before the model sees anything and returns the page as state rather than prose: "Published September 15, 2026" becomes "2026-09-15", "$42 per billion tokens" becomes { value: 42, unit: "USD_per_billion" }, and the text is cut into chunks that each know their size in tokens and the #anchor on the page where an answer can be checked.
Who it is for
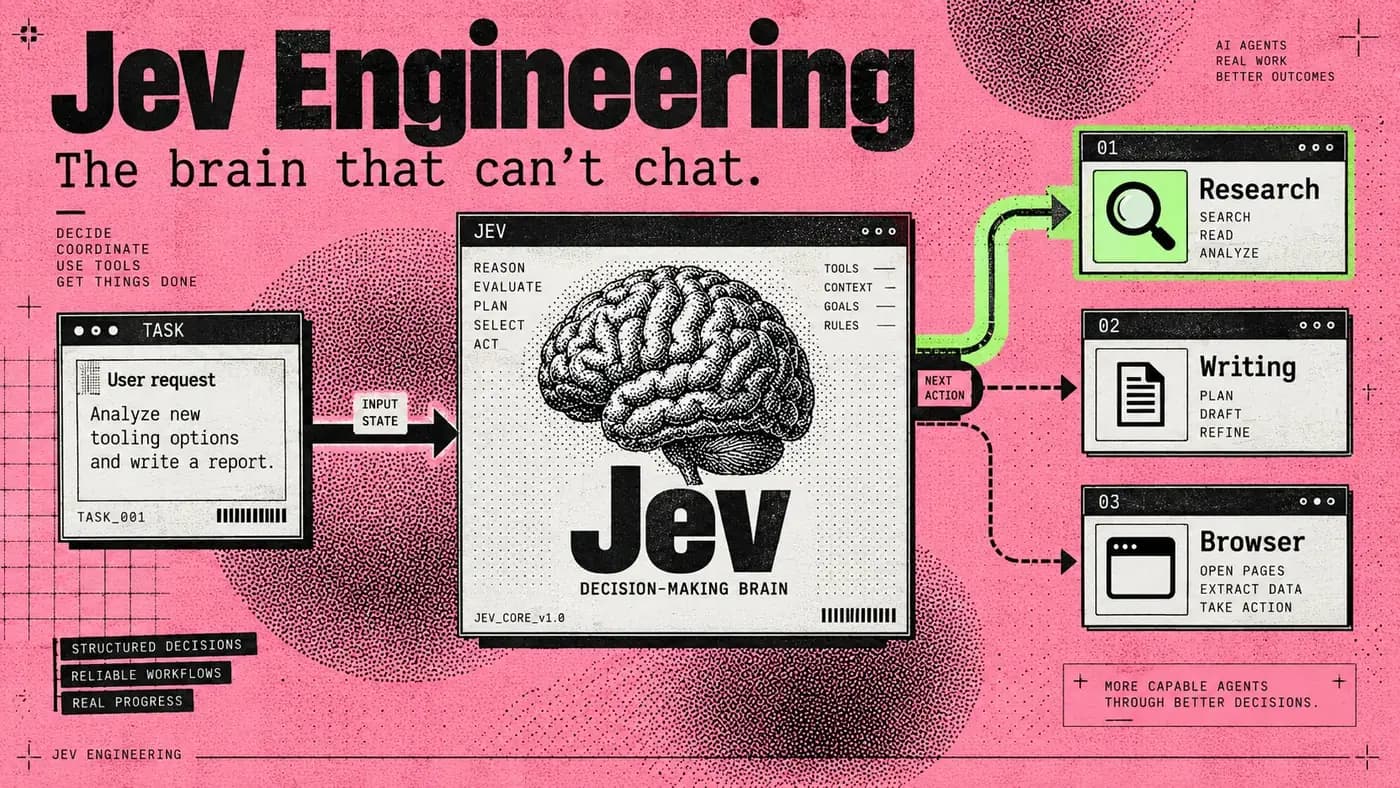
The difference from "page to markdown" tools is who the output is for. They prepare input for a reader; this one prepares input for a judge: cheap decision models like Jev, which do not write but classify and score, cannot count, read dates as strings and lose accuracy as irrelevant material fills the context. Eight steps of ordinary code, no model and no API key; the same HTML gives the same JSON. Expected failures do not throw, they come back as named warnings: robots-disallowed, blocked, http-error, paywall, empty-without-js, thin-content, block-split, facts-capped.
What we measured
What we measured ourselves on 21 September 2026 across 56 random pages: a median token saving of 98.5 %, a mean of 91.3 %, the median page 53 718 tokens in and 1 106 out, 1.1 s per page at the median and 3.5 s at the 90th percentile, 50 of 56 pages usable, nine languages. The output was then put in front of Jev: 11 of 11 extracted facts verified automatically at a confidence of 0.86 to 1.0, and 6 of 6 page types classified correctly. A run over 50 pages with Jev as the judge costs about $0.002; the same pages as raw HTML would cost about $8.60 in Sonnet and about $43 in Opus.
Where it stops, and how to install
Where it stops is in the README rather than hidden: front pages and listings give you headlines and thin-content, articles rendered by JavaScript come back as empty-without-js, and a pricing grid does not know which plan column a number sits under, so the parser does not guess. It installs in one line as an MCP server for Claude Code or Cursor (npx -y codearia-sieve), exposes two tools, sieve_page and sieve_chunk, or comes in as a library with npm i codearia-sieve. 69 tests, all offline.
Comments