Articles
Breakdowns of tools, repositories and approaches — every piece dated and version-checked
39pieces
Less code, more tests: Ponytail teaches Claude Code to stop writing what you don't need
Build with Claude Code without hundreds of extra lines: install Ponytail, walk its ladder of questions, the pre-release review and the author's benchmark.
BreakdownClaude Code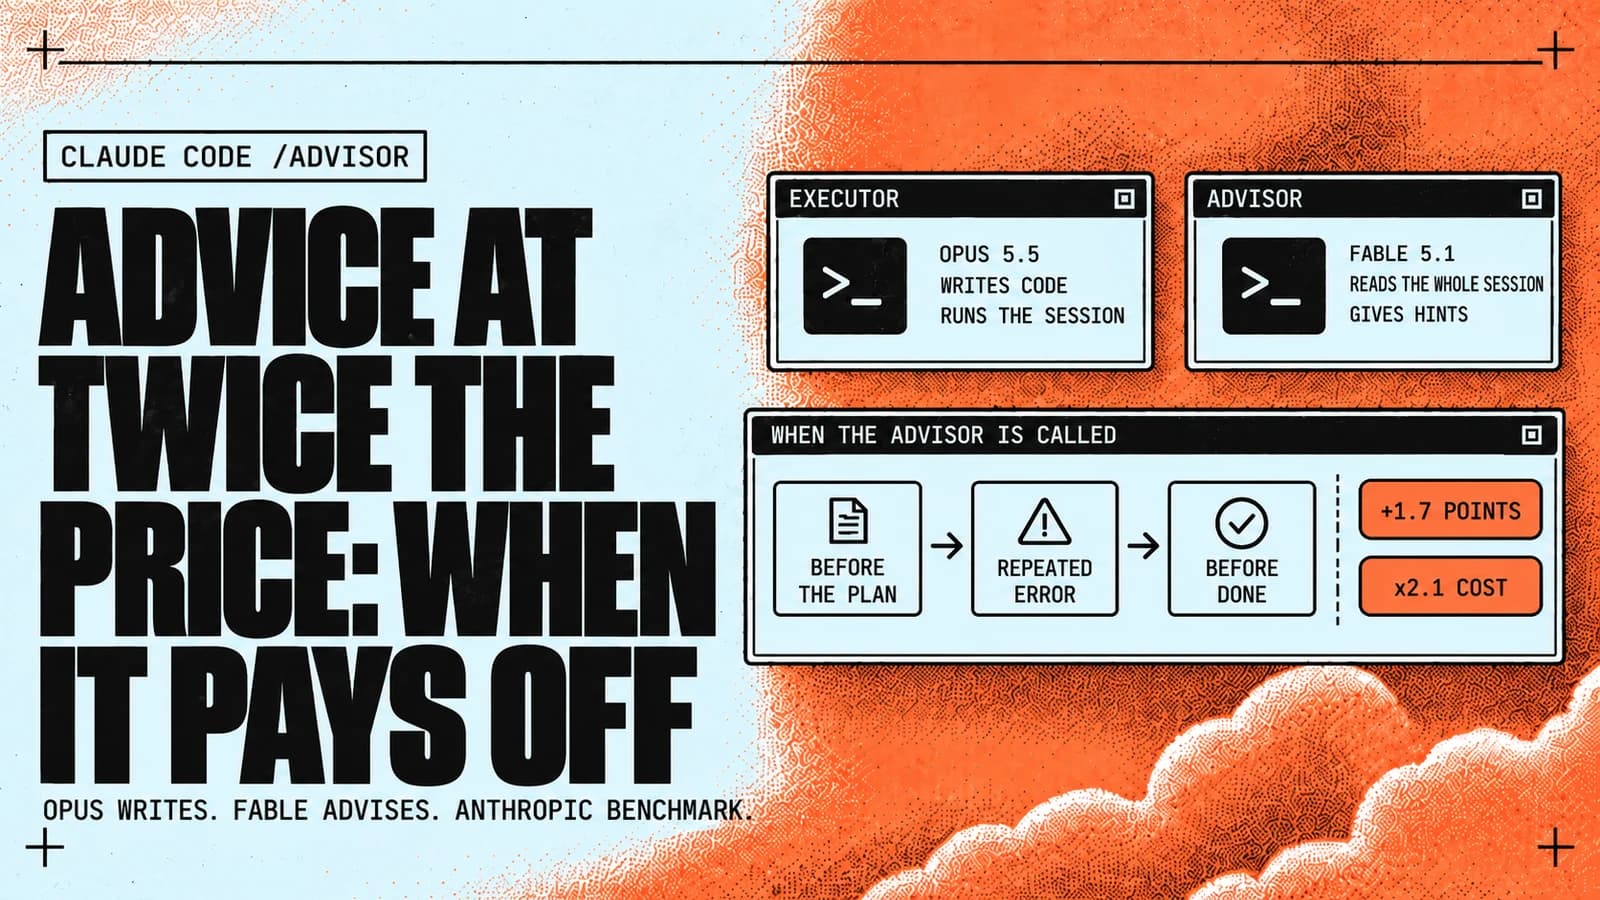
Fable 5.1 as an advisor adds just 1.7 points to Opus 5.5 at twice the cost. So when does /advisor pay off?
Imagine Opus 5.5 writing the code while Fable 5.1 steps in at the hard parts. Anthropic measured +1.7 points for about 2.1x the cost. Here is where it pays.
BreakdownClaude Code
57 tokens per second instead of 30 on the same Mac. How does Magnitude beat llama.cpp?
Can a local model run your agent twice as fast with no new hardware? We break down Magnitude: kernels tuned to your chip, and where llama.cpp is still faster.
BreakdownAI Agents
The skill that grew into Cloudflare's 7,245 bug findings. What will it find in your repository?
Can you trust Claude Code with a security audit? Cloudflare open-sourced a skill where a different agent checks every finding. Its phases, setup and gaps.
BreakdownClaude Code
Hindsight writes its own wiki about your repository. Does Claude Code need that kind of memory?
Teach Claude Code and Codex to remember why the project works the way it does: how Hindsight works, where its 94.6% comes from and which defaults to change.
BreakdownClaude Code
GPT-6 Sol is half the price of Opus 5.5 per token. So why is a task only 20% cheaper?
On the price list GPT-6 Sol costs exactly half of Claude Opus 5.5. On a task in an independent test it is only 21% cheaper and 3 points weaker. Here is why.
BreakdownAI Agents
Agents now get a boss, a task queue and a budget. Do you need one if you already work in Claude Code?
Five Claude Code and Codex windows in one task queue with roles and budgets: that is Paperclip. Where it helps, and where its spending cap kicks in late.
BreakdownAI Agents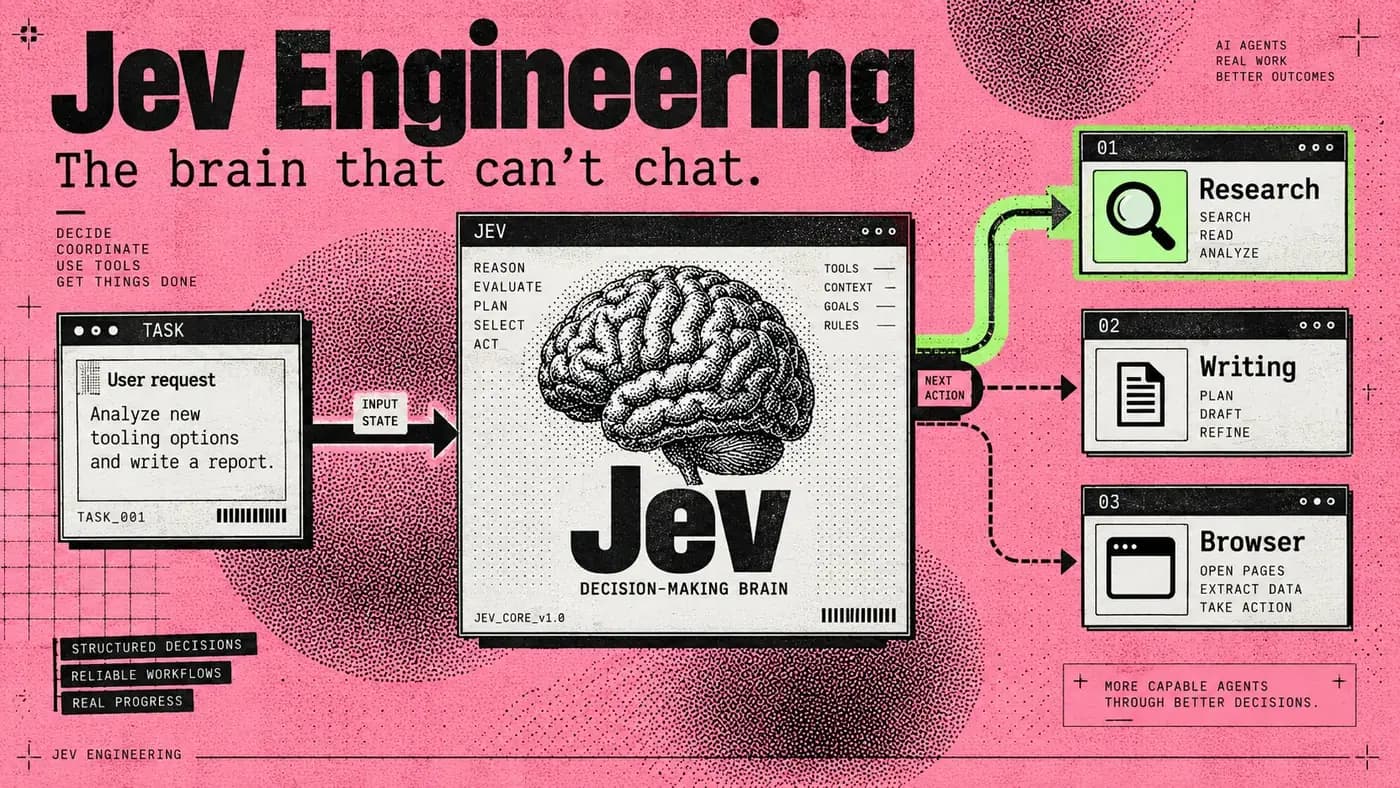
The model that will take 70% of the decisions away from ordinary LLMs. What is Jev?
Imagine a model that generates no text at all: you hand it state and typed questions, and you get values with probabilities back in a hundredth of a second. That is Jev, launched on 15 September. We go through the numbers from the source, where it fits inside an agent, and the nine places its own authors say it fails.
BreakdownAI Agents
Same model, same success rate, twice the money. What are you actually paying Claude Code for?
Imagine paying for a model twice: once for the intelligence, once for the way it is served to you. Berkeley ran seven models through three harnesses. On one pairing Claude Code came out three times more expensive and twelve points worse. We break down where that tax comes from, and where the study does not apply to your work.
BreakdownAI Agents
One key instead of a dozen: what Monid does, and how many tools are really in there?
Imagine your agent no longer needing your account at every service: it finds a fitting endpoint itself, sees the price and the latency before calling, and pays only for what came back. That is Monid, released this week. We installed it, ran the tests, found a Windows bug and counted the catalogue by hand.
BreakdownAI Agents
Don't choose between Claude Fable 5.1 and GPT-6 Astra until you've answered one question
Imagine Anthropic's smartest model shipping on a Monday, and OpenAI answering on Wednesday with its own and declaring the AGI era. Both cost $10 per million input tokens and $50 per million output, to the cent. Then the differences start: one spends its tokens working out what is going on, the other spends them getting things done. We pulled together the benchmarks, the subscription prices, an independent robot-arm test and what both companies admitted about themselves, so you can pick a model for your work rather than for a headline.
BreakdownClaude Code
caveman: a third off your tokens by having the agent read less
A project whose motto tells you everything: "why many token when few token also trick". What it actually cuts, what the benchmark shows, and why the licence matters more here than the savings figures.
BreakdownClaude Code