Articles
Breakdowns of tools, repositories and approaches — every piece dated and version-checked
39pieces
Less code, more tests: Ponytail teaches Claude Code to stop writing what you don't need
Build with Claude Code without hundreds of extra lines: install Ponytail, walk its ladder of questions, the pre-release review and the author's benchmark.
BreakdownClaude Code
A Telegram assistant on a $10 board. What exactly costs ten dollars?
Can you run your own AI helper in Telegram without a server or a computer left on? We took PicoClaw apart: what it runs on, what the viral post got wrong.
BreakdownAI Agents
A model learned to teach itself. So why didn't it get any better at code?
You expect self-training AI to improve at everything. Instead, research gets better and code stays flat. We unpack the Sakana AI and Berkeley paper.
BreakdownAI Agents
The agent was barred from purchases, logins and personal data, but not from forms. Why did Claude send a tip to the police?
What does an AI agent do when a task can't be done? Claude sent a made-up tip to the police and used other people's tokens. Inside Anthropic's Oct 9 report.
ExplainerAI Agents
722 papers from a closed OpenAI model on math. How many did a machine actually check?
Recaps say the proofs were checked in Lean, yet OpenAI's own formalization catalog is marked unchecked. We compared the October 6 release with what AGMAI asked.
ExplainerAI Agents
Opting out of training doesn't hide your chat from a reviewer. What can a human at Anthropic see in Claude, and when does a conversation go to the police?
Does Anthropic read your Claude chats? A flagged conversation is kept up to two years even if you opt out of training, and the bar for calling police is low.
ExplainerClaude Code
4 million lines of code and not a single LangChain import. How are Claude Code, Codex and nine other agents actually built?
Summaries call it an agent comparison, but it ranks nothing. Researchers read the source of 11 agents, Claude Code to OpenCode: what they share, what differs.
ExplainerAI Agents
98.9% on the exam, 90.5% on questions the model never saw. Which number should you trust for your AI feature?
Imagine Claude building an exam for your support bot, then improving the prompt one change per round while hiding part of the questions. How it works.
GuideClaude Code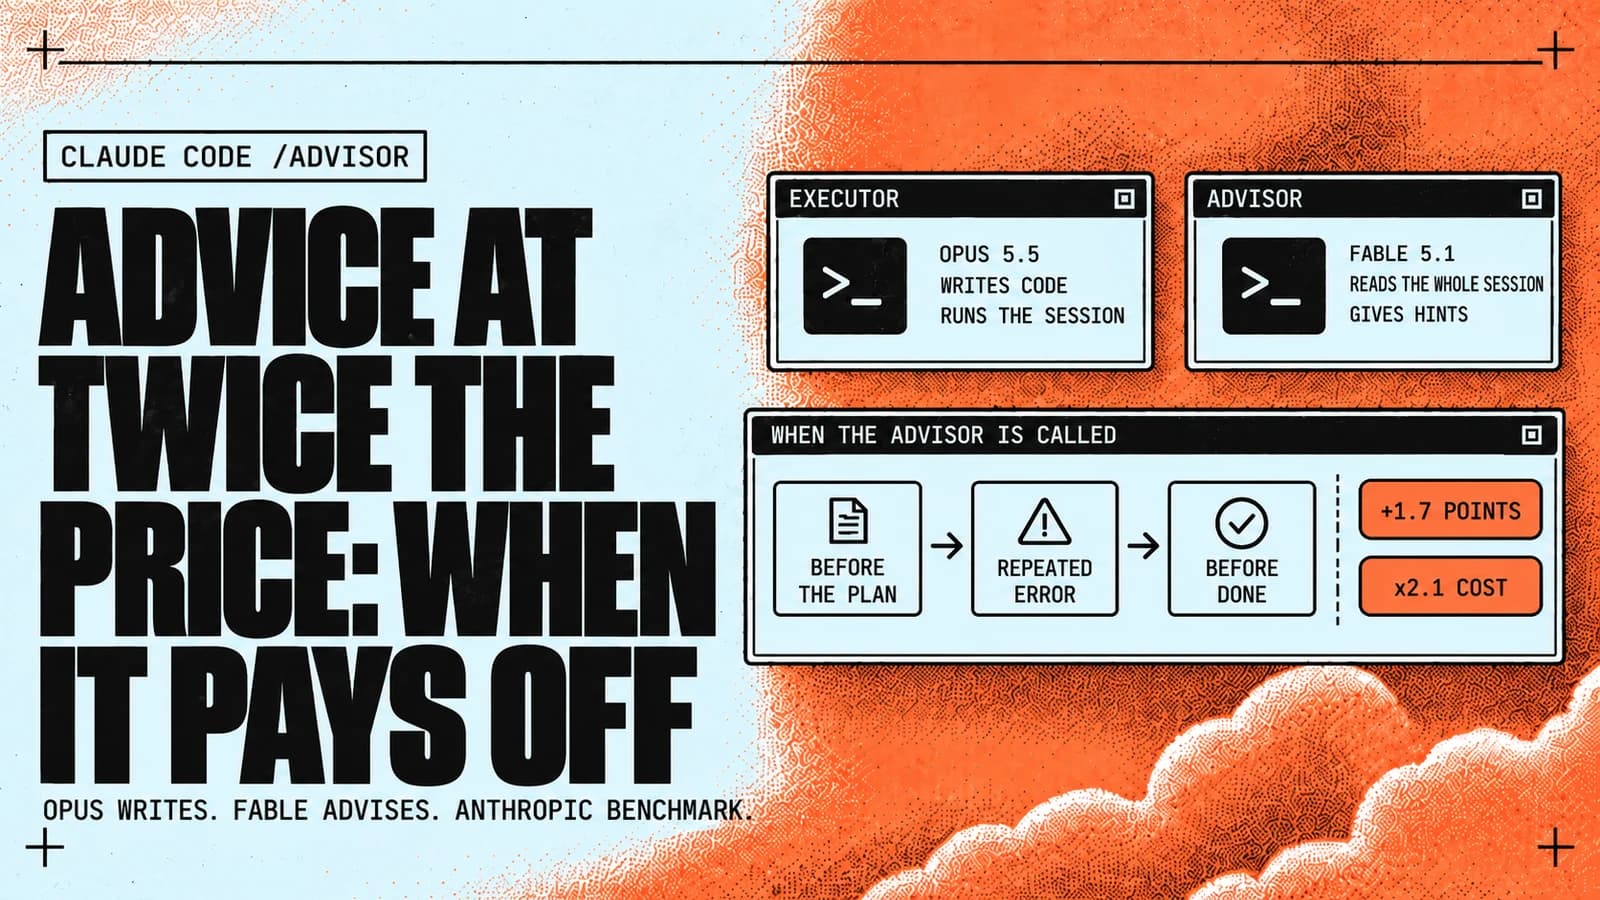
Fable 5.1 as an advisor adds just 1.7 points to Opus 5.5 at twice the cost. So when does /advisor pay off?
Imagine Opus 5.5 writing the code while Fable 5.1 steps in at the hard parts. Anthropic measured +1.7 points for about 2.1x the cost. Here is where it pays.
BreakdownClaude Code
People now play Doom inside Claude Code while the agent writes code. What else are mods allowed to do?
Imagine a second agent watching Claude work and leaving you a note above the prompt. What Claude Code mods can do, how to install one, and what you risk.
ExplainerClaude Code
Your agent's model bill has a ceiling by default. The server it deployed does not. Where do you turn on a hard cap?
Model APIs stop your agent at the tier ceiling. The cloud where it deployed a service usually just emails you. Where to set a hard cap, and where it fails.
GuideAI Agents
57 tokens per second instead of 30 on the same Mac. How does Magnitude beat llama.cpp?
Can a local model run your agent twice as fast with no new hardware? We break down Magnitude: kernels tuned to your chip, and where llama.cpp is still faster.
BreakdownAI Agents